Retrieval analysis
BM25 (lexical), dense (sentence embeddings), and hybrid (reciprocal rank fusion) retrieval, compared per-metric across the 35 gold-bearing v1 tasks, followed by the reranking stage and its recall ceiling.
Per-metric comparison
A precision-of-rank-1 vs. total-recall tradeoff is visible in the raw numbers: BM25 has the highest MRR (0.498) of the three retrievers despite the lowest Recall@10 (0.643) — exact lexical matches are more likely to rank the single best document first when they hit. Dense has the opposite pattern (Recall@10 0.769, the highest of the three, MRR 0.472, the lowest) — embeddings surface more relevant documents somewhere in the top 10 without necessarily ranking the best one first. This directional pattern is descriptive, not bootstrap-confirmed on its own — see the significance table below for which of these differences actually clear a 95% CI.
What the bootstrap tests actually confirm
| Comparison | Metric | Result |
|---|---|---|
| hybrid vs dense | recall_at_10 | Not distinguishable from noise |
| hybrid vs bm25 | recall_at_10 | 95% CI excludes zero |
| hybrid vs dense | ndcg_at_10 | Not distinguishable from noise |
| hybrid vs bm25 | ndcg_at_10 | Not distinguishable from noise |
| hybrid vs dense | mrr | Not distinguishable from noise |
| hybrid vs bm25 | mrr | Not distinguishable from noise |
Full mean-diff / CI values are on the benchmark leaderboard. RQ2 (does hybrid beat dense?) is answered no, not significantly even at n=35 — only hybrid-vs-BM25 clears significance.
Reranking: effect and ceiling
RQ4 asks when reranking helps, decomposed into first-stage recall (the ceiling a reranker cannot exceed) vs. reranker precision. Cross-encoder reranking on top of hybrid first-stage retrieval:
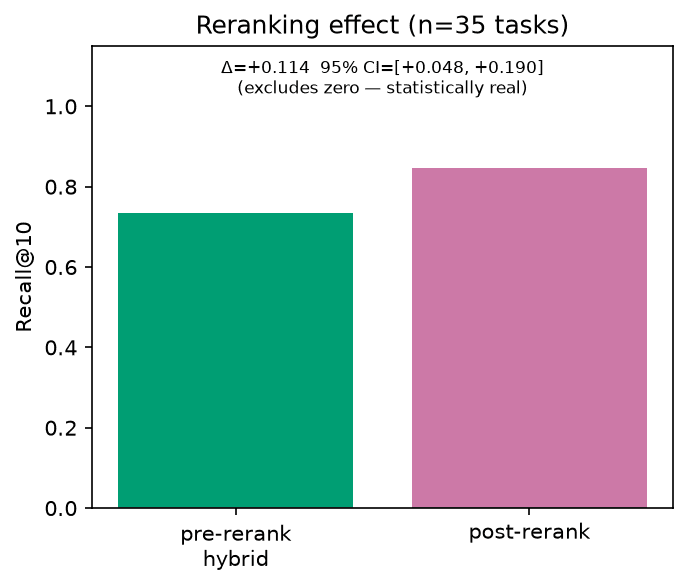
~11% of gold evidence is never retrieved by hybrid at all within the top 20 candidates — by construction, no reranker downstream can recover it. This is a retrieval-miss propagating forward, not a reranker defect.
- Recall@5
- 0.636
- Recall@10
- 0.848
- MRR
- 0.613
- nDCG@10
- 0.621
Pipeline
- 1. BM25 (lexical baseline)
- 2. Dense (biomedical sentence embeddings)
- 3. Hybrid (reciprocal rank fusion of BM25 + dense)
- 4. + Cross-encoder reranking (ms-marco-MiniLM-L-6-v2) on hybrid’s top-20 pool